01
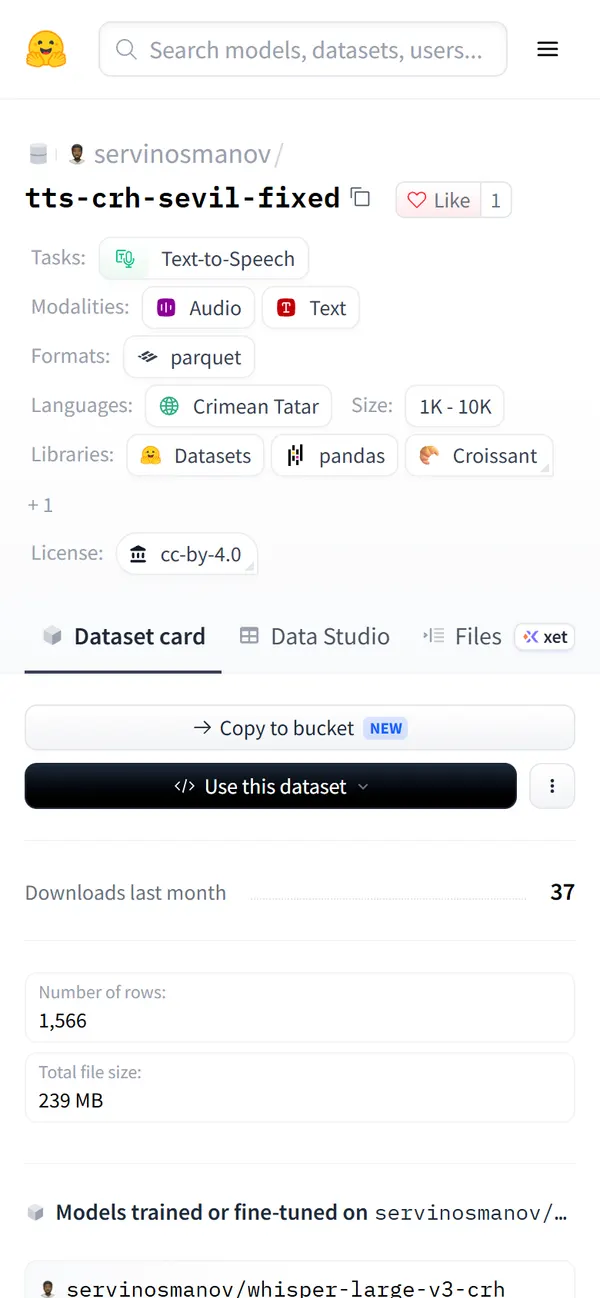
Sevil voice dataset
1,566 corrected recordings with transcripts, split into training, validation and test sets. Licence: CC BY 4.0.
Big services barely support this language. This project collects real voices and builds the first models: one reads text aloud, the other turns speech into text.
Major voice services barely support Crimean Tatar. This project collects real voices and builds the first open models: one reads text aloud, the other turns speech into text.
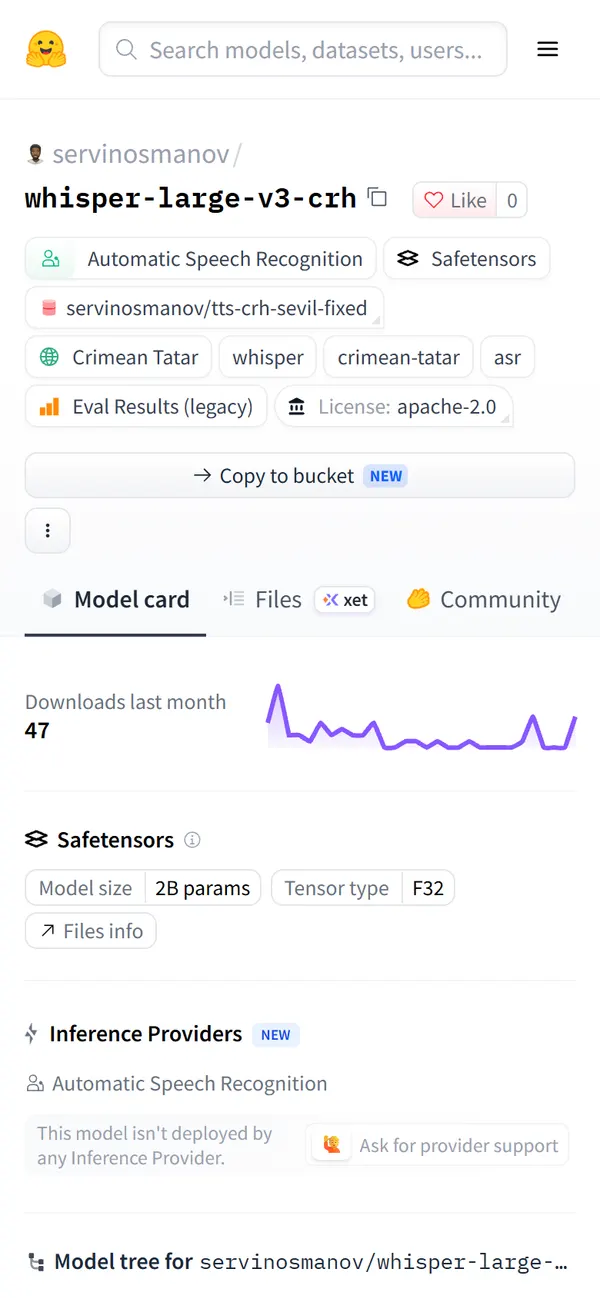
It is built on a dataset of 1,566 recordings of Sevil’s voice, about 2.6 hours of speech. Only 415 files in the original set were usable; now all of them are fixed: noise, volume, pauses and transcripts. SpeechT5 (text-to-speech) and Whisper Large v3 (speech recognition, word error rate 13.7%) were fine-tuned on these recordings.
A whole novel has already been read with the synthesized voice: Shamil Alyadin’s “Merdiven”, 16 chapters, almost two hours. All models and data are open (CC BY 4.0 and Apache 2.0) and can be built into your own apps.
A dataset of corrected voice recordings.
The first model that reads text aloud.
The first model that turns speech into text.
1,566 corrected recordings with transcripts, split into training, validation and test sets. Licence: CC BY 4.0.
Whisper Large v3 fine-tuned on Crimean Tatar. It handles both Cyrillic and Latin script; word error rate is 13.7%.
Who makes it: Servin Osmanov (Ana Yurt).
Found a mistake? Write to us and we will fix it in the next update.
selam@ocaq.ru